
The Law Inside the Machine: Building the NeuroAI Future by Design
Earlier this month, I attended the NIH BRAIN Initiative Conference in Washington, DC, where I presented my poster on advancing neurodata stewardship for secondary analysis. At the centre of my poster was a deceptively simple proposition: technically portable data are not necessarily governably reusable data. A dataset may be downloadable, stored in a recognised format and accompanied by sufficient technical documentation. But that does not necessarily tell a future researcher whether the proposed reuse is consistent with the participant’s consent, which institution retains responsibility for the data, whether the data may cross borders, or how withdrawal and benefit-sharing obligations should be managed. Standing beside the poster, I was therefore already thinking about the distance between making data available and making their reuse responsible.
As I moved through the conference sessions, however, it became clear that this distance is about to become considerably more important. The future being imagined was not simply one in which neuroscientists have access to more brain data or use artificial intelligence to analyse it more efficiently. It was a future of federated data archives, AI agents navigating scientific resources, neural foundation models, digital twins, embodied intelligence, and adaptive brain-computer interfaces.
It was a vision in which data do not merely travel. They are combined, interpreted, and transformed into models that may eventually predict, recommend and act. And underneath many of the scientific diagrams was another layer: ethics, governance, security, accountability, and sustainability. Law was not standing outside the laboratory, waiting to regulate whatever emerged. It was already being drawn into the architecture of discovery.
The future is not a bigger database
It is tempting to describe the next phase of neuroscience as a data problem.
Researchers are producing enormous quantities of information across different levels of the brain, including molecular data, cell atlases, neural recordings, brain images, behavioural measurements, and data generated by neurotechnological devices. Connecting these resources may allow researchers to ask questions that cannot be answered by any single dataset.
But the conference vision extended beyond creating a very large repository.
Instead, it imagined a federated knowledge environment with independently managed data archives connected through a common layer that helps scientists, and increasingly AI systems, discover and use the resources distributed across them. In such an environment, a researcher might pose a question in ordinary language. An AI agent could locate relevant datasets, examine metadata, connect evidence across repositories and perhaps initiate an analytical workflow. In time, agents may help generate hypotheses or contribute to the construction of multimodal models and digital representations of biological systems. This could transform neuroscience. It could also transform the meaning of data access.
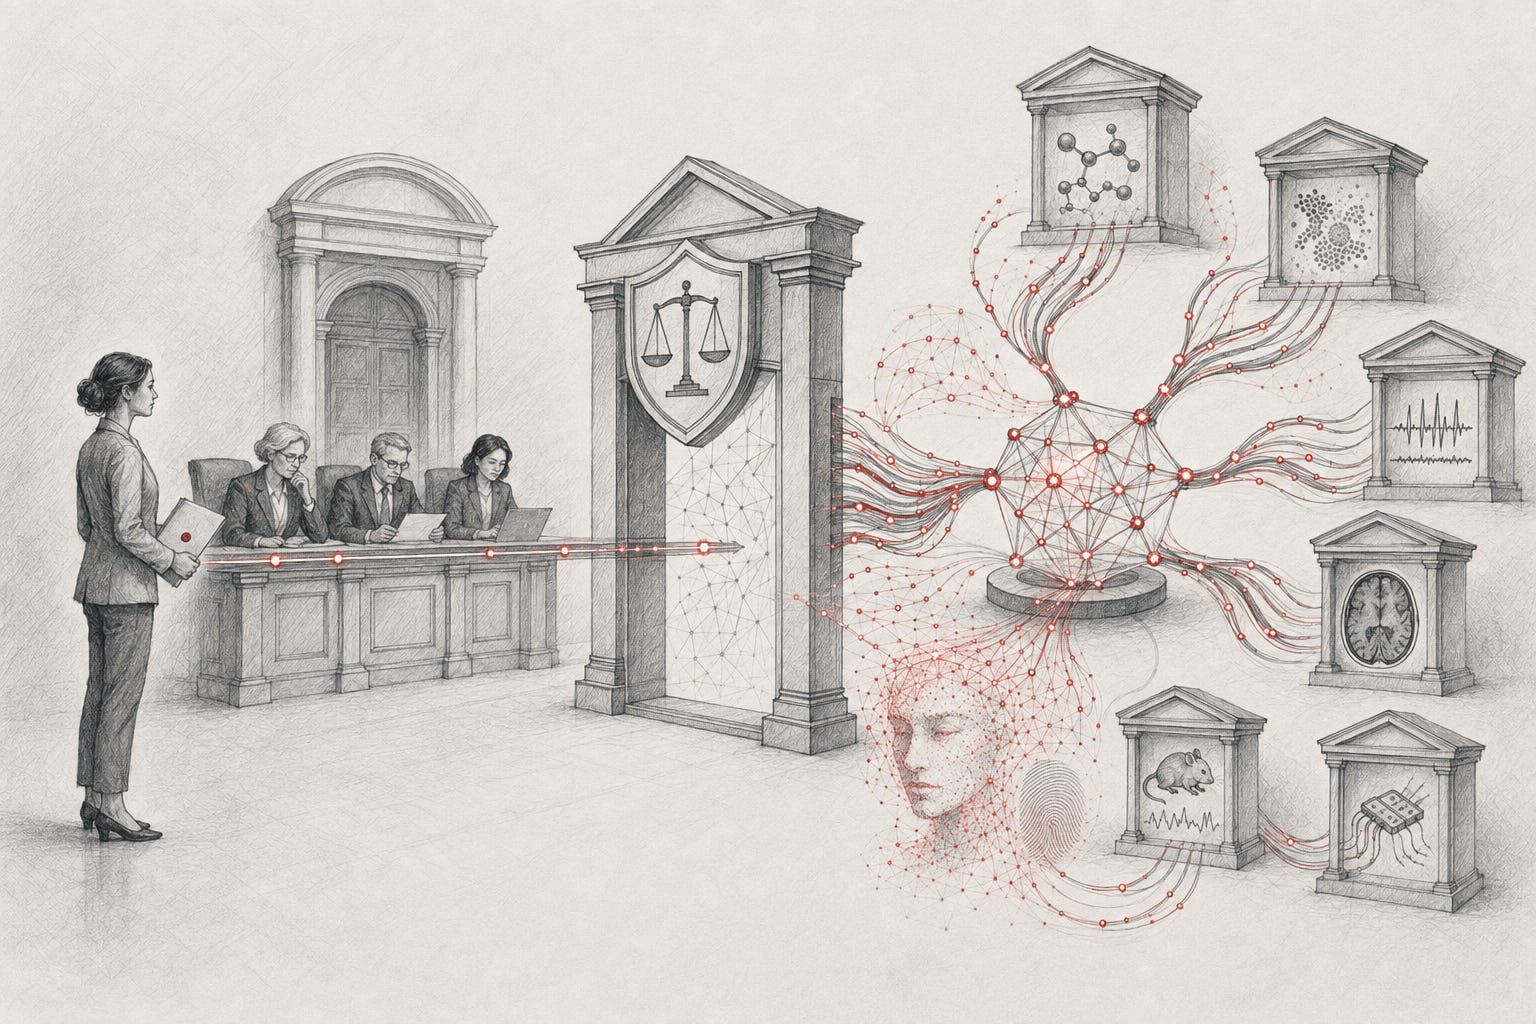
Historically, access governance has often centred on a human researcher submitting an application to a data access committee (so-called DACs). The researcher explains the proposed purpose, identifies the data required and agrees to certain conditions. Human reviewers then decide whether the proposed use is permissible. But what happens when the applicant is effectively an AI agent? What happens when it can submit, reformulate and combine queries at machine speed? What happens when no single repository contains identifying information, but an agent can infer sensitive information by connecting several resources? And what happens when the original conditions of consent are recorded in decades-old documents that neither the agent nor the researcher can reliably interpret? These are not questions that can be answered through faster computing alone.
From governance documents to governance infrastructure
Much of research governance currently exists in documents.
Consent forms describe what participants agreed to. Data-management plans describe how information should be handled. Data-transfer agreements define permitted uses. Ethics approvals establish the conditions under which a project may proceed. These documents remain legally and ethically important. But they were generally written for human interpretation, frequently for a particular study conducted at a particular moment. The NeuroAI environment being imagined will require some of these conditions to travel with the data in forms that computational systems can recognise. Consent terms, permitted uses, withdrawal status, provenance, access restrictions and attribution requirements may need to become structured parts of a dataset’s metadata. An agent seeking access should be able to determine that a dataset may be used for research into a particular condition, but not for commercial profiling or an unrelated secondary purpose.
This is not entirely speculative. The Global Alliance for Genomics and Health has developed Machine-Readable Consent Guidance that maps consent language to standardised data-use terms. Although developed for genomic and health data, the underlying insight is highly relevant to neuroscience: participant choices cannot govern future reuse if they become detached from the data as those data travel.
Machine-readable consent should not, however, be confused with machine-decided consent. Converting legal and ethical conditions into computable categories does not eliminate ambiguity, context or the need for human judgment. Not every future use can be reduced to a simple “permitted” or “prohibited” label. Consent may have been shaped by relationships of trust, expectations about public benefit, community values or understandings of harm that cannot be captured adequately in a standardised code.
The purpose of machine-readable governance should therefore be to help systems comply with human decisions, not to allow systems to replace those decisions.
One trust layer, two moments of governance
One of the most useful distinctions raised at the conference was between governance at the time an AI system is trained and governance at the time it is used. These are related, but they are not the same problem. At training time, the questions concern the origins and legitimacy of the model:
Were the data collected and shared lawfully? Were the proposed uses consistent with consent? Can the sources be traced? Are some populations overrepresented while others are absent? Were cross-border restrictions respected? Who is entitled to benefit from the resulting model? What happens if a participant later withdraws?
At agent time, the questions shift to what the system is allowed to do:
Which repositories may it search? Which queries may it make? May it combine data from different sources? Could its repeated queries create a new re-identification risk? How are its actions recorded? When must it refer a decision to a human authority? Who is accountable when it generates an unsupported or harmful conclusion?
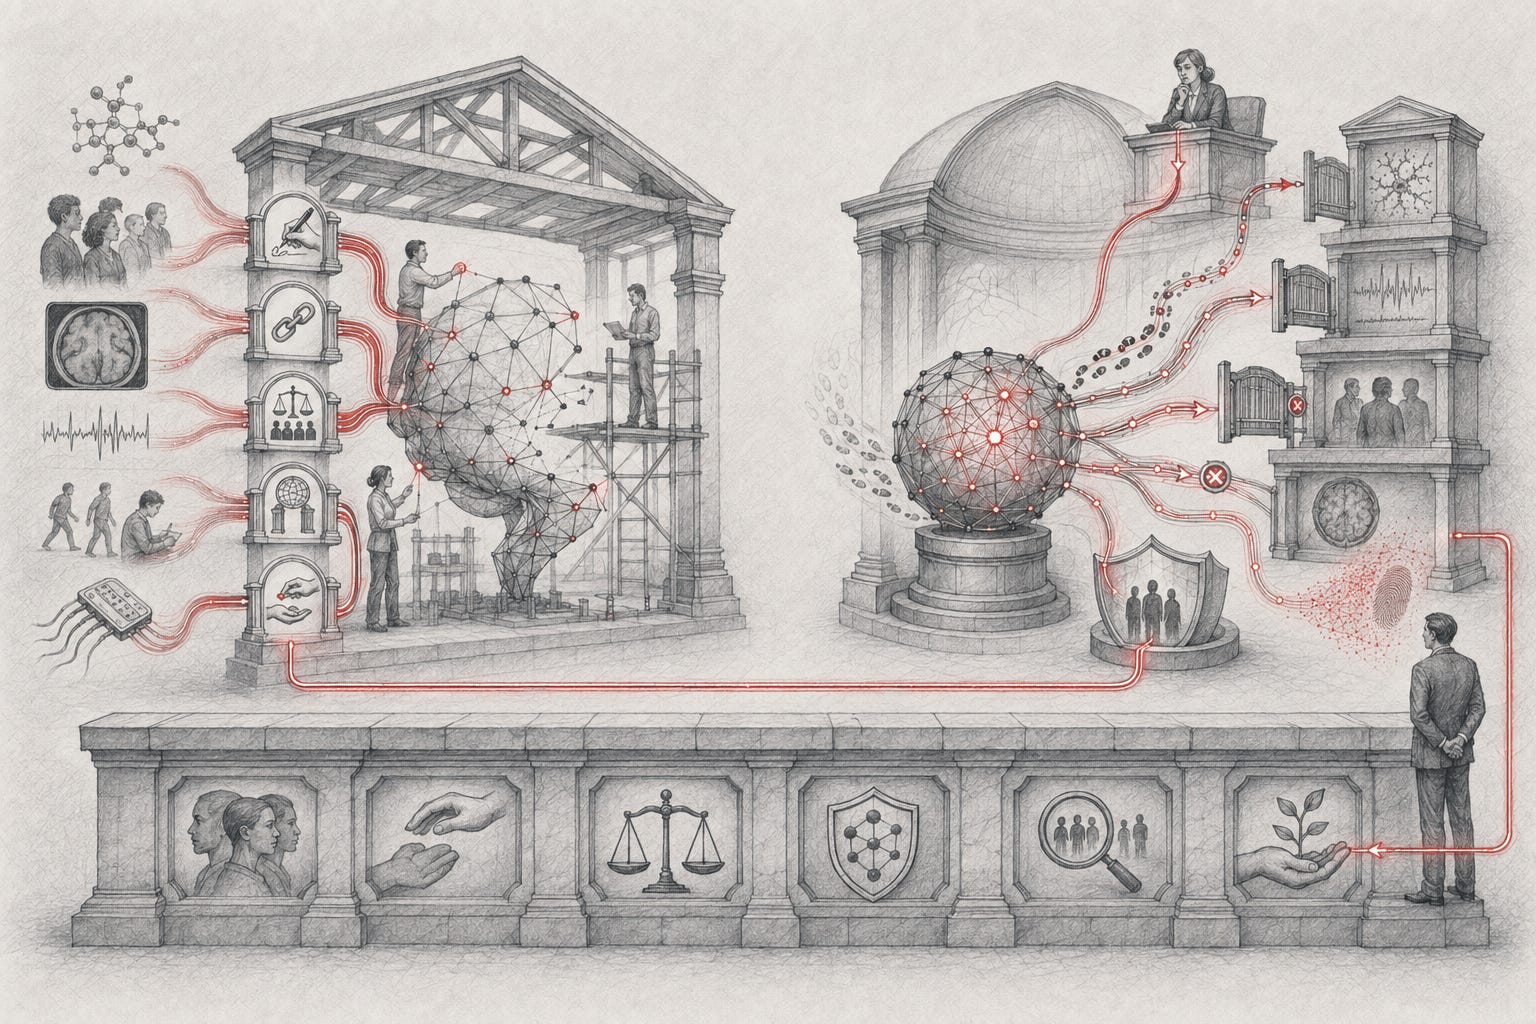
NeuroAI therefore requires a common foundation of trust, but at least two distinct governance designs, one governing how intelligence is created and another governing how that intelligence behaves. This distinction matters because a model trained on lawfully obtained data is not automatically lawful or ethical in every later use. Equally, strict control over an AI agent’s behaviour cannot repair a model whose underlying training data were collected unfairly, documented inadequately or used beyond the scope of consent. Governance must follow the entire chain.
What gets benchmarked gets built
One sentence from the conference has stayed with me:
What gets benchmarked gets built.
Benchmarks help scientific communities decide what counts as progress. If NeuroAI systems are evaluated primarily according to accuracy, speed and computational efficiency, developers will understandably optimise for those qualities. But a highly accurate system can still be unaccountable. A fast system can violate consent more efficiently. A powerful model can reproduce the blind spots of an unrepresentative dataset at previously impossible scale. Governance should therefore become part of how scientific performance is evaluated. A genuinely trustworthy NeuroAI system might also be assessed according to whether it:
-
respects consent and data-use restrictions;
-
maintains traceable links to its sources;
-
withstands modern re-identification attacks;
-
performs reliably across different populations;
-
identifies uncertainty and evidentiary gaps;
-
records the actions taken by AI agents;
-
preserves appropriate attribution;
-
recognises when human review is required; and
-
provides meaningful routes for challenge, correction and redress.
This is where law can play a constructive role. Legal principles such as purpose limitation, accountability, transparency, and non-discrimination can help determine what the scientific community chooses to measure. Rights tell us what ought to be protected. Governance translates those protections into responsibilities. Benchmarks help us determine whether the system being built can fulfil them.
Whose law enters the machine?
Embedding governance into infrastructure creates its own dangers. Once a legal interpretation has been translated into a data standard, access rule or automated decision pathway, it can become difficult to see and even more difficult to contest. This raises a particularly important question for global neuroscience: whose law, whose ethics and whose understanding of legitimate research use will be encoded?
Brain data may be collected in one country, stored in another, processed using infrastructure located in a third and incorporated into a model deployed internationally. The relevant jurisdictions may have different rules regarding consent, privacy, data sovereignty, public interest, and commercialisation. The differences are not only legal. Communities may understand the brain, mind, identity, and personhood in different ways. A standard designed by well-resourced institutions in the Global North may travel easily across borders while failing to carry these differences with it.
There is consequently a risk that “interoperability” becomes another word for requiring everyone else to fit the categories developed by the most technologically powerful participants.
A lawful and ethical infrastructure must remain open to plurality, explanation and challenge. It requires meaningful participation by the communities whose data make neuroscience possible. It requires clearly identified human authorities, transparent change-control procedures and routes through which decisions can be questioned.
This is one reason the UNESCO Recommendation on the Ethics of Neurotechnology is significant. It adopts a human-rights-based and human-centred approach across the entire neurotechnology lifecycle, while also recognising equality, cultural diversity, scientific freedom, and benefit sharing. Governance by design must not become ethics hidden in code. The values encoded in the system must remain visible, contestable and capable of revision.
Law as infrastructure, not obstruction
Discussions about emerging technology often portray law as a brake: science advances, law falls behind, and regulation eventually arrives to limit what technology can do. The conference suggested a different relationship.
Federated neuroscience cannot function sustainably without agreement about authority, responsibility, and shared standards. AI agents cannot navigate research resources responsibly without reliable rules governing access and use. Models cannot remain trustworthy without provenance, validation, and mechanisms for correction. Participants will not continue contributing data if institutions cannot demonstrate that their choices remain meaningful after their data have entered complex computational environments. Law is therefore not only a mechanism for preventing harm. It can create the conditions under which responsible collaboration becomes possible.
The NIH BRAIN Initiative’s Neuroethics Guiding Principles have long recognised that neuroethics is integral to scientific progress. They connect innovation with safety, autonomy, neural-data privacy, public dialogue, justice and the fair sharing of benefits. The next step is to translate that integration into infrastructure. This means investing not only in spectacular models and powerful computing, but also in the less visible connective tissue, namely standards, stewardship, documentation, consent representation, validation, security, audit mechanisms, and the people who maintain them. It also means funding governance as a continuing scientific function rather than treating it as a temporary compliance exercise completed at the beginning of a project.
Building a machine capable of remembering
Returning to my poster, I was reminded that secondary data use depends on a form of institutional memory. When data move beyond the original research team, someone, or increasingly some system, must remember where they came from, what participants were told, which uses were permitted, what limitations remain and who is responsible for the next decision.
NeuroAI will increase the speed and scale at which neuroscience can make connections. But speed makes this memory more important, not less. The future presented in Washington was extraordinarily ambitious: connected archives, AI-assisted discovery, foundation models, digital twins, and eventually adaptive neurotechnologies capable of operating in real time. Realising that future will require data, compute, and scientific daring. It will also require law to move from the margins of innovation into its foundations. The challenge is not simply to place legal rules inside a machine. It is to build scientific systems that can carry consent, provenance, accountability, and human values forward, even as their technology changes.
The question is therefore not whether law will slow the machine. It is whether we are willing to build a machine capable of remembering the law, the people, and the purposes that made its knowledge possible.
Stay curious,
Marietjie